Category / ai developer tooling
AI developer tooling
Practical work with agents, MCP, RAG, LLM APIs, and evaluation systems.
Giving an AI Agent a Memory: Patterns, Storage, and What to Forget
Build a practical memory layer for an AI agent, choose where each kind of memory lives, and design retrieval and forgetting that you can trust.
Chunking Strategies for Embeddings: What Actually Changes Retrieval Quality
Compare fixed-size, recursive, semantic, and structure-aware chunking so you can choose a strategy that improves retrieval instead of quietly breaking it.
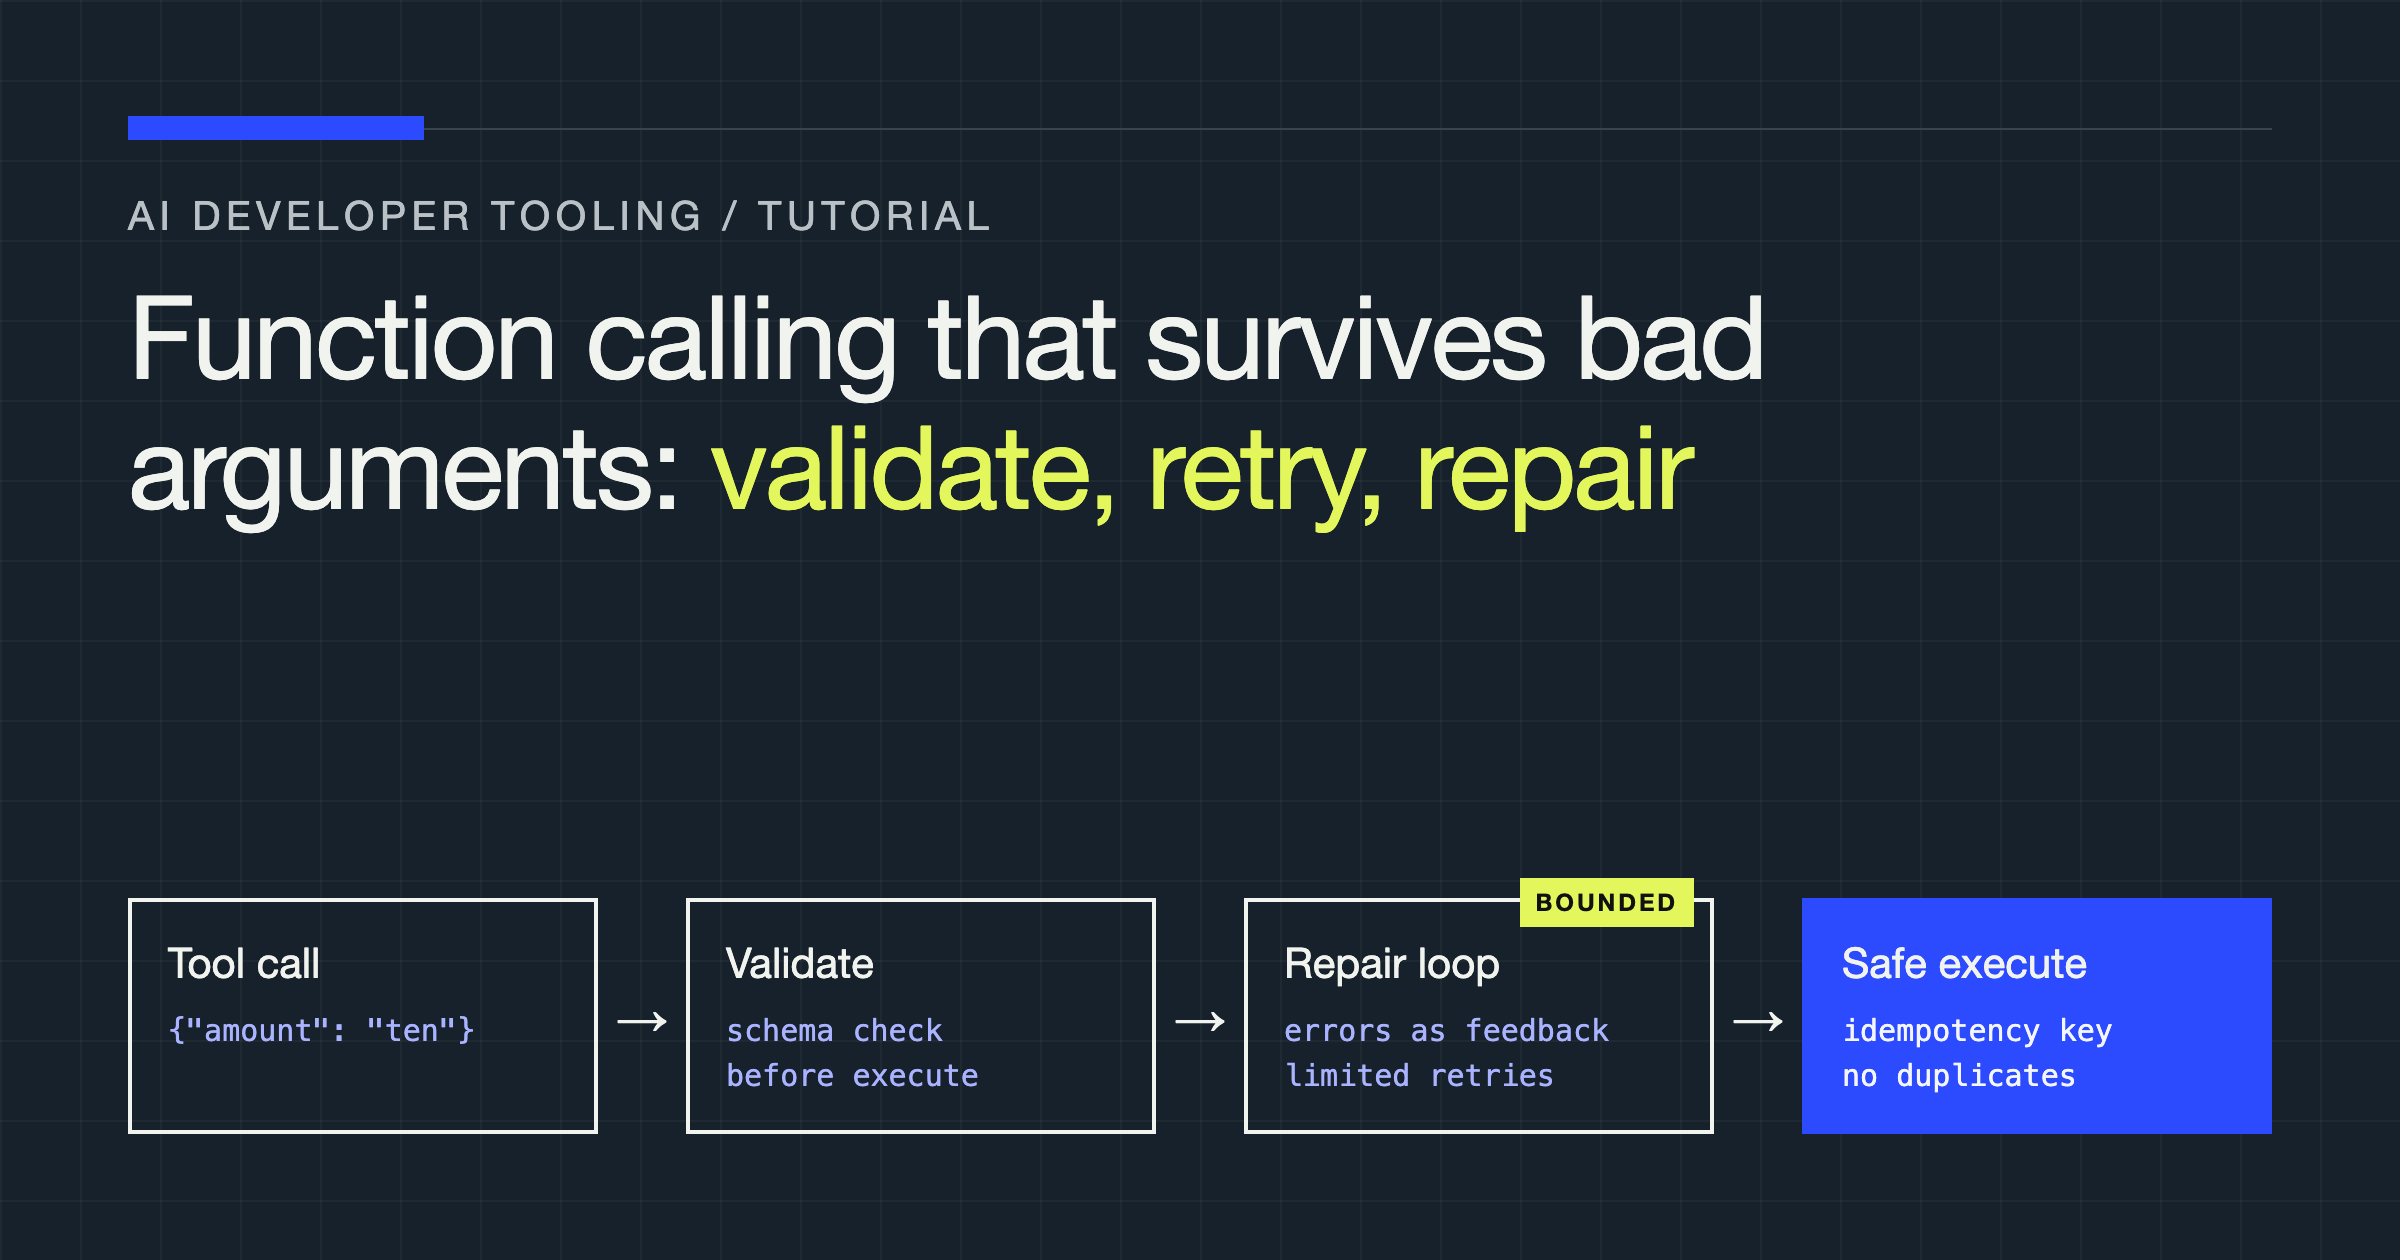
Function Calling That Survives Bad Arguments: Validation, Retries, and Repair
Build a validation, retry, and repair layer for LLM function calling that rejects bad arguments, returns useful errors, and protects side effects.
Cache LLM Responses Without Serving Stale Answers
Design an LLM response cache that actually saves money: exact-match keys, versioned prompts, tenant isolation, and the strict rules for when semantic caching is safe.
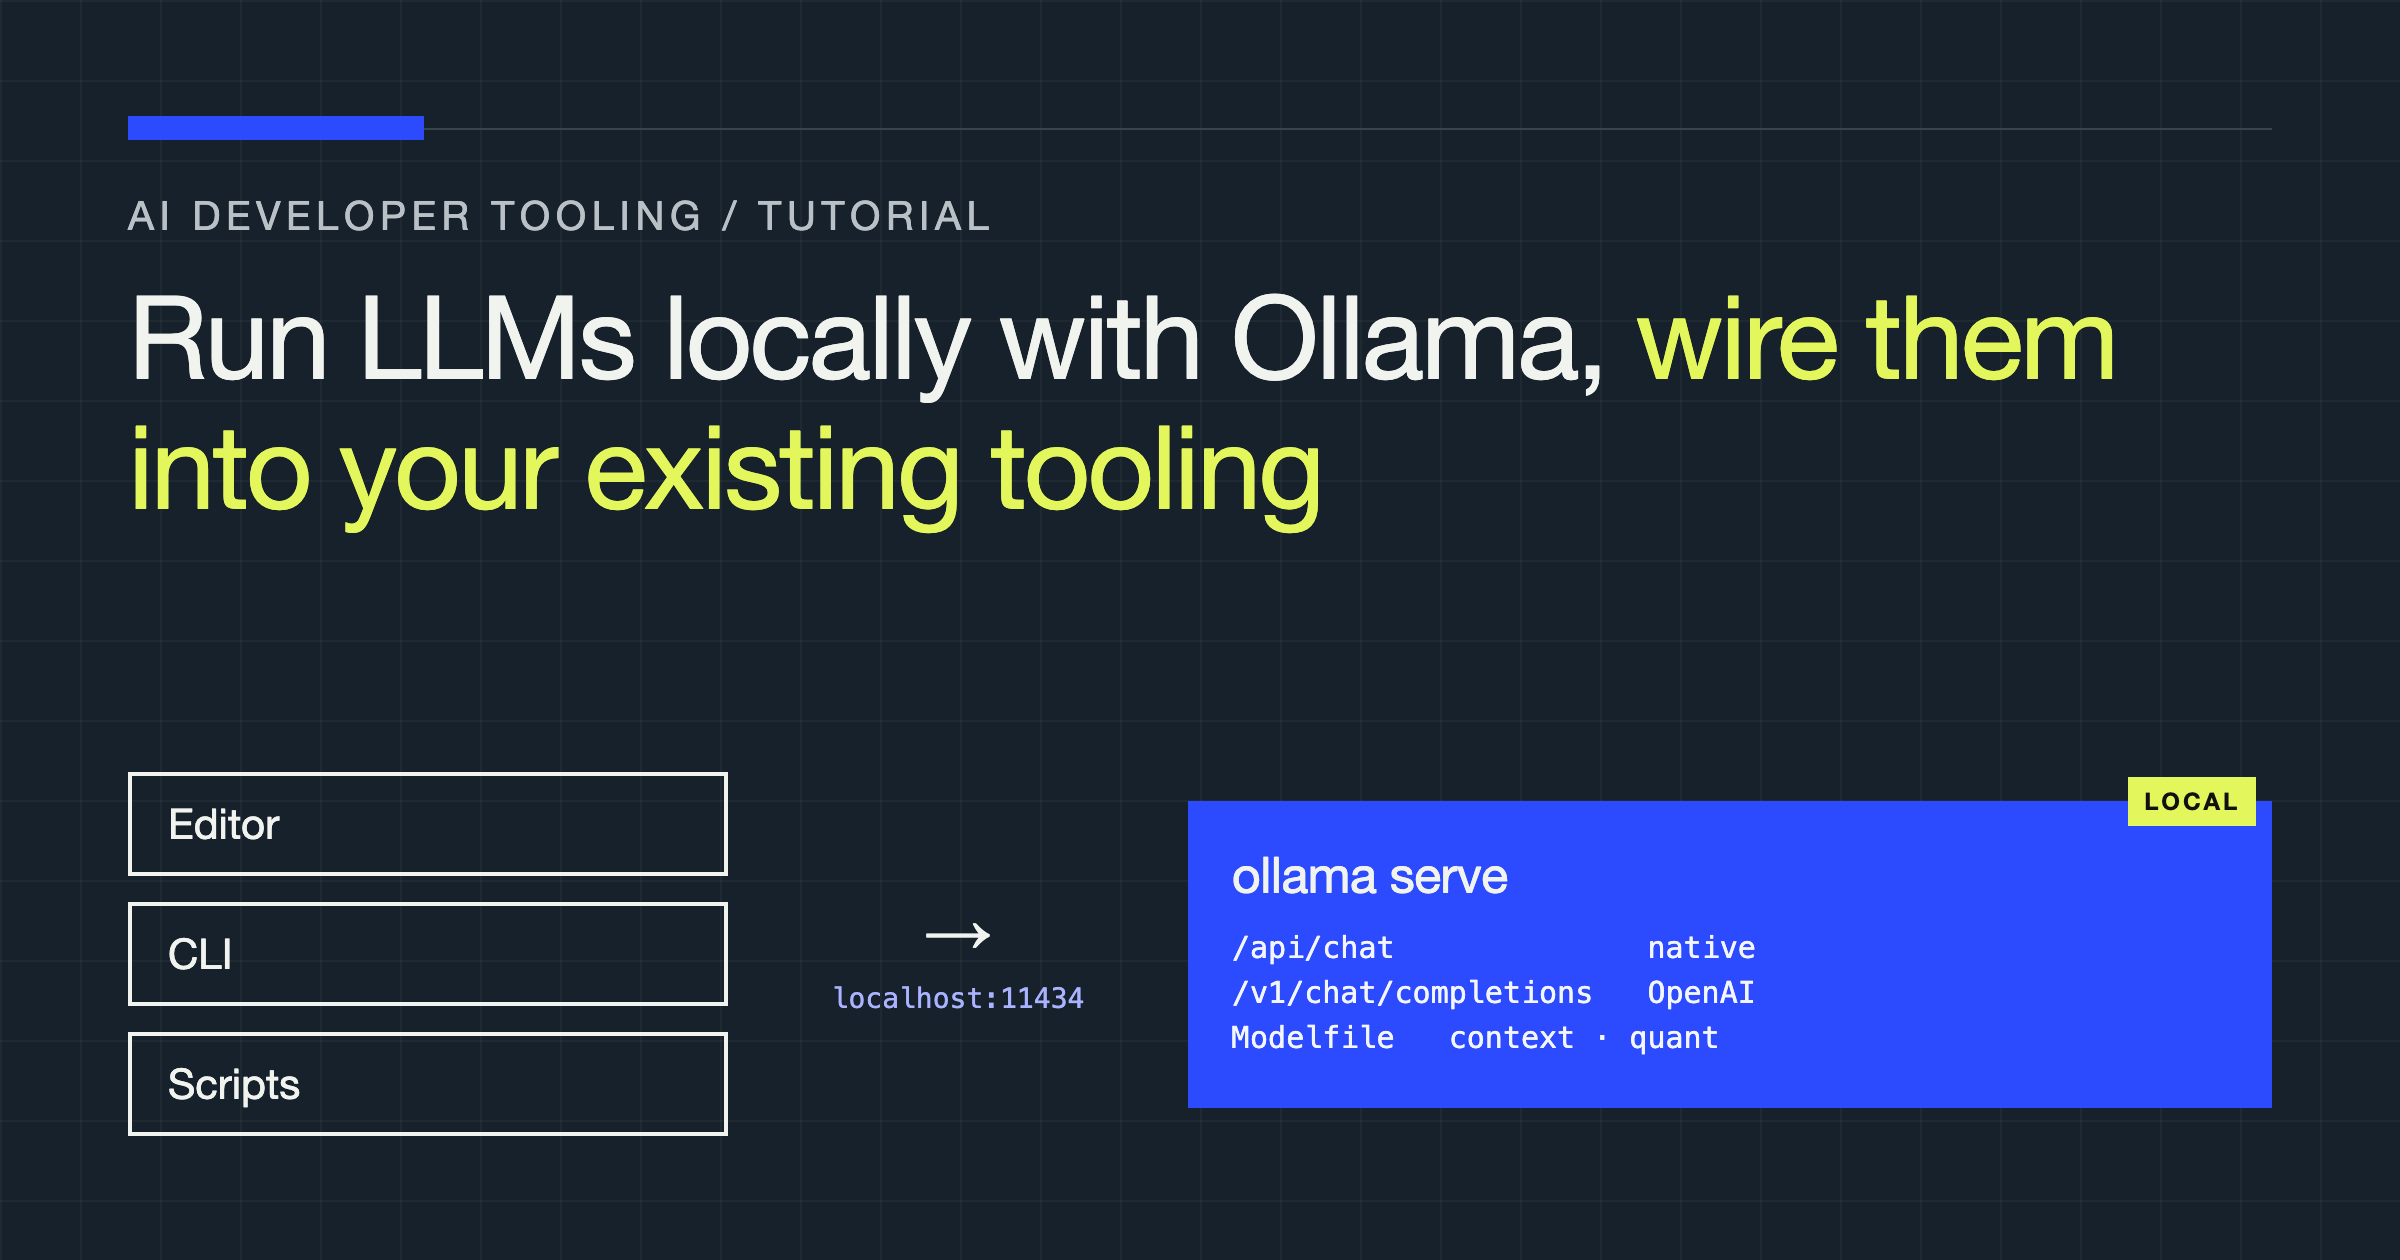
Run LLMs Locally with Ollama and Wire Them into Your Existing Tooling
Install Ollama, serve models over its native and OpenAI-compatible APIs, tune context and quantization, and connect editors, CLIs, and scripts.
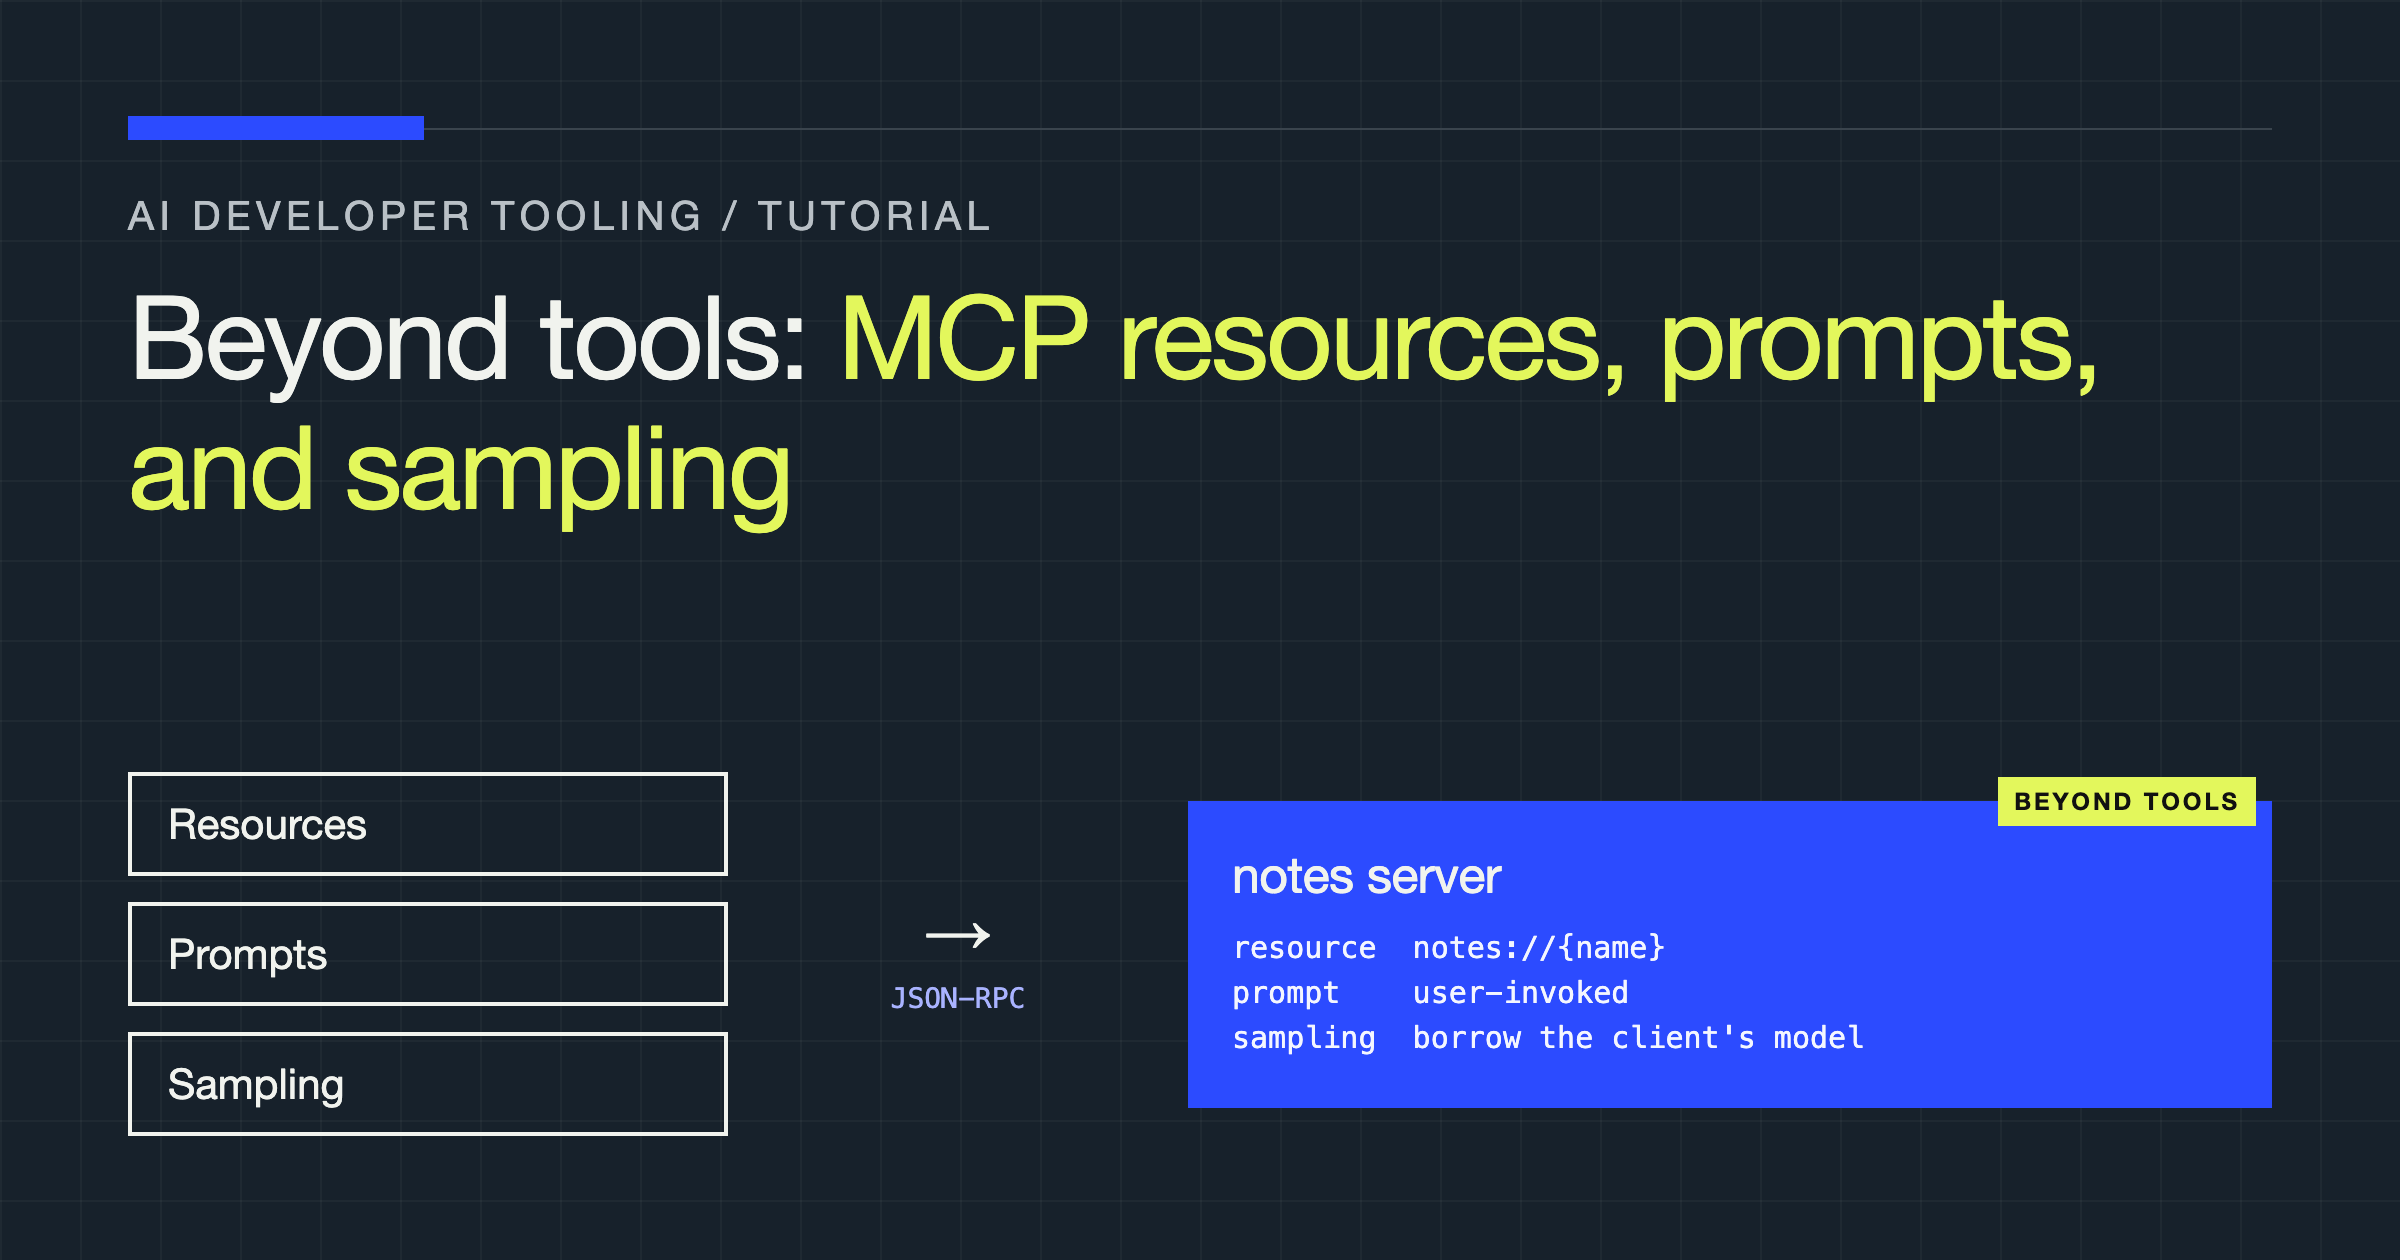
Beyond Tools: MCP Resources, Prompts, and Sampling, Explained by Building
Tools get all the attention, but MCP's resources, prompts, and sampling are what make a server feel native. Build a small server that uses all three.
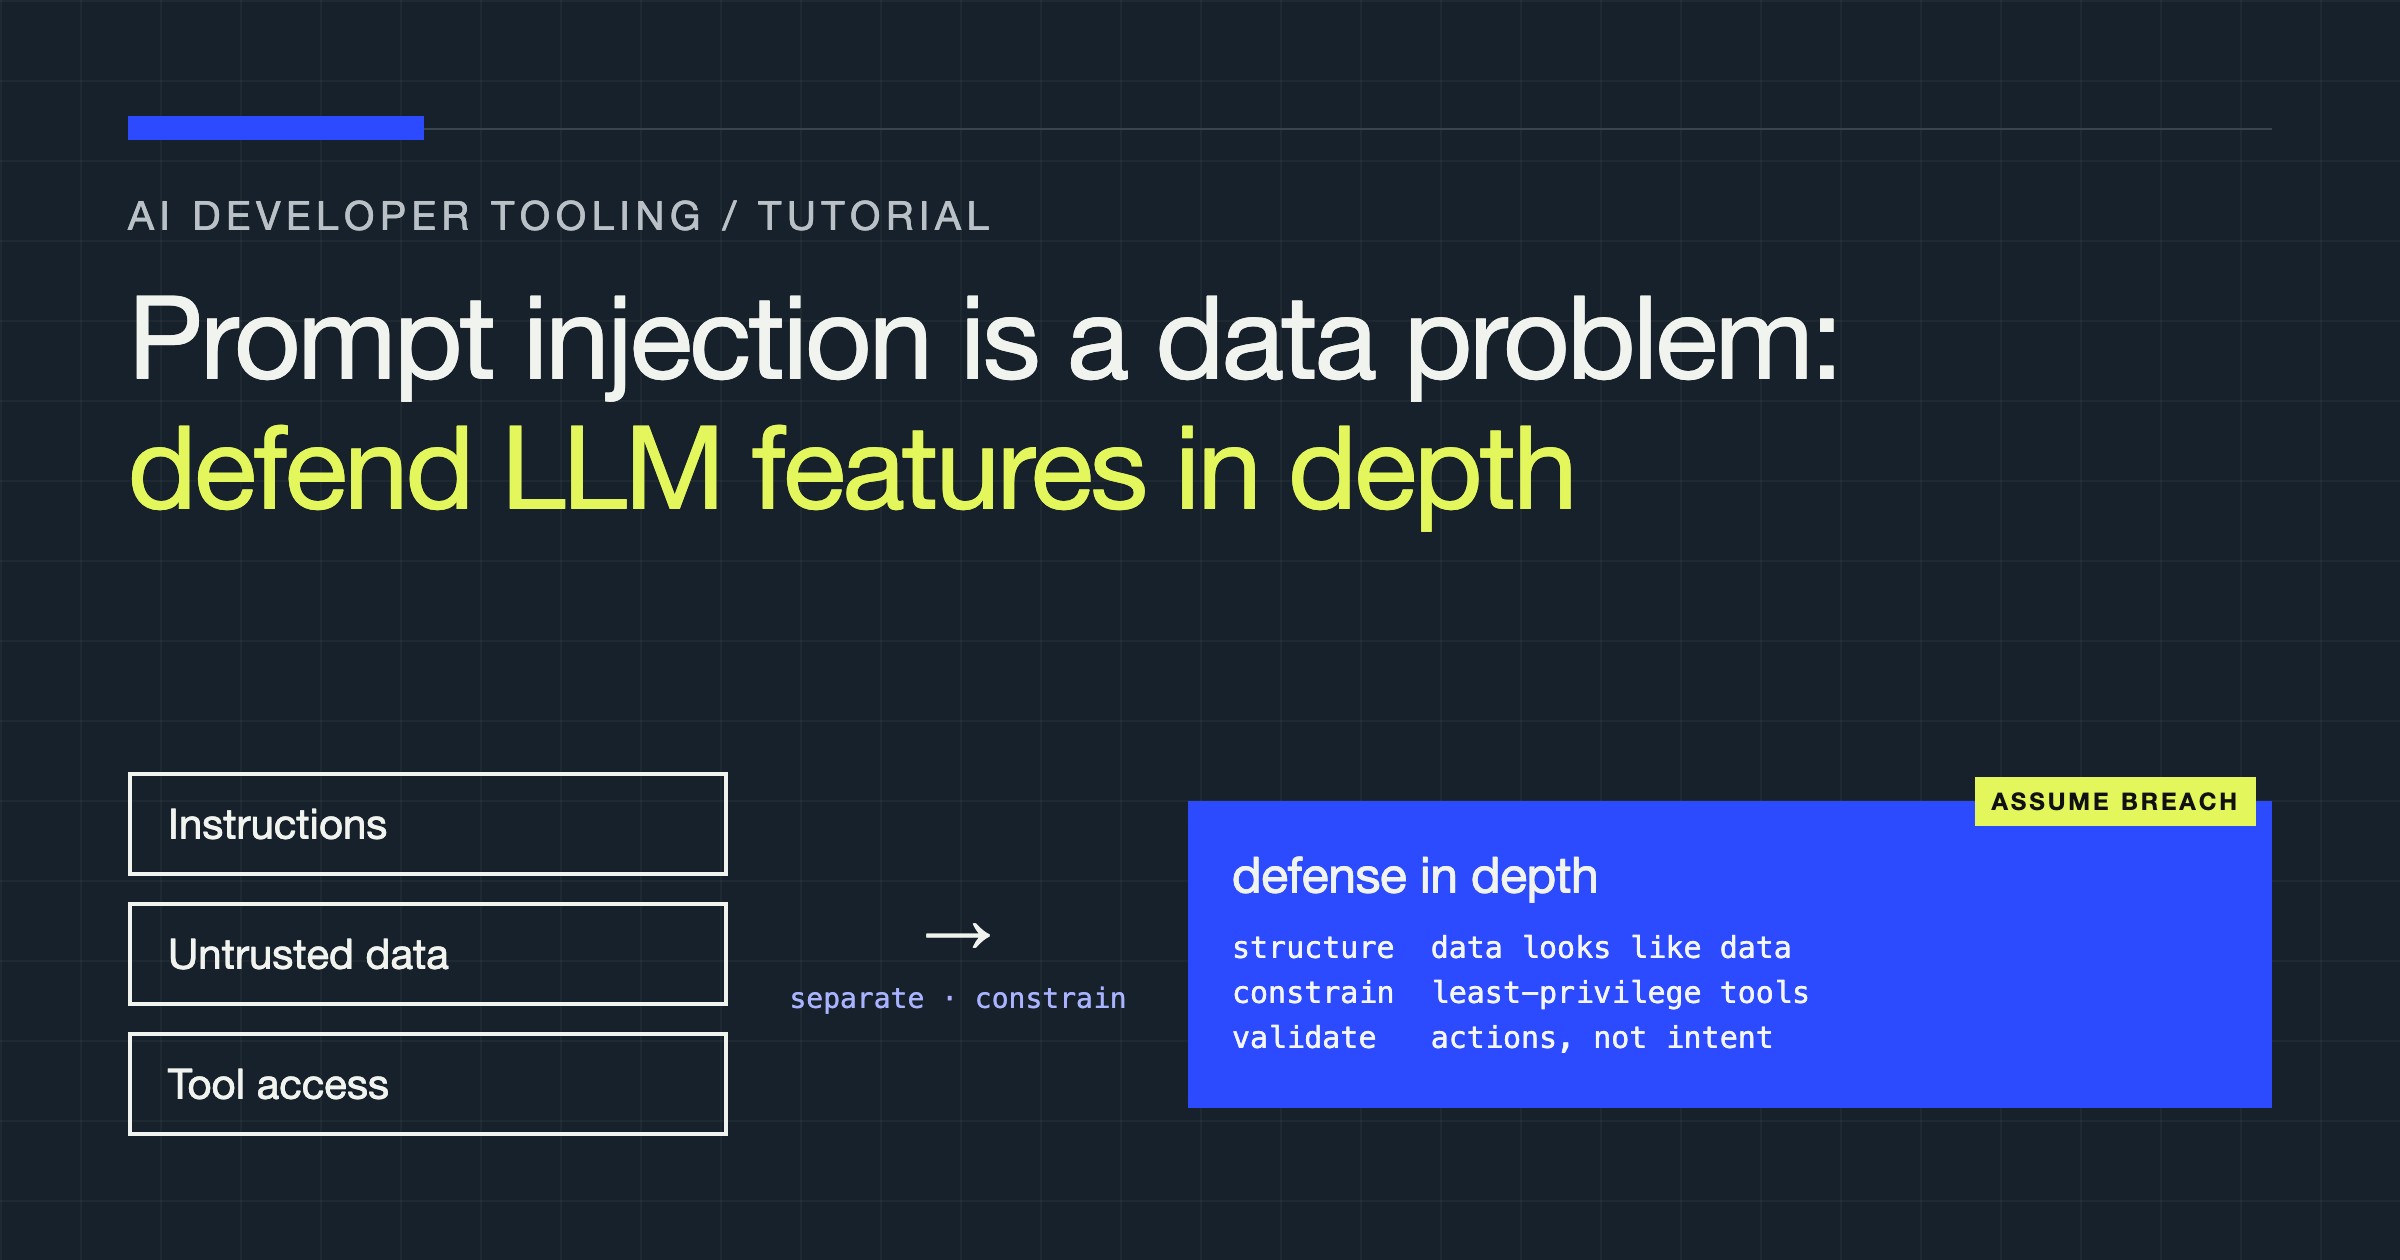
Prompt Injection Is a Data Problem: Defending LLM Features in Production
Prompt injection works because models cannot tell instructions from data. Defend in depth: separate the two, constrain tools, validate actions, and assume breach.
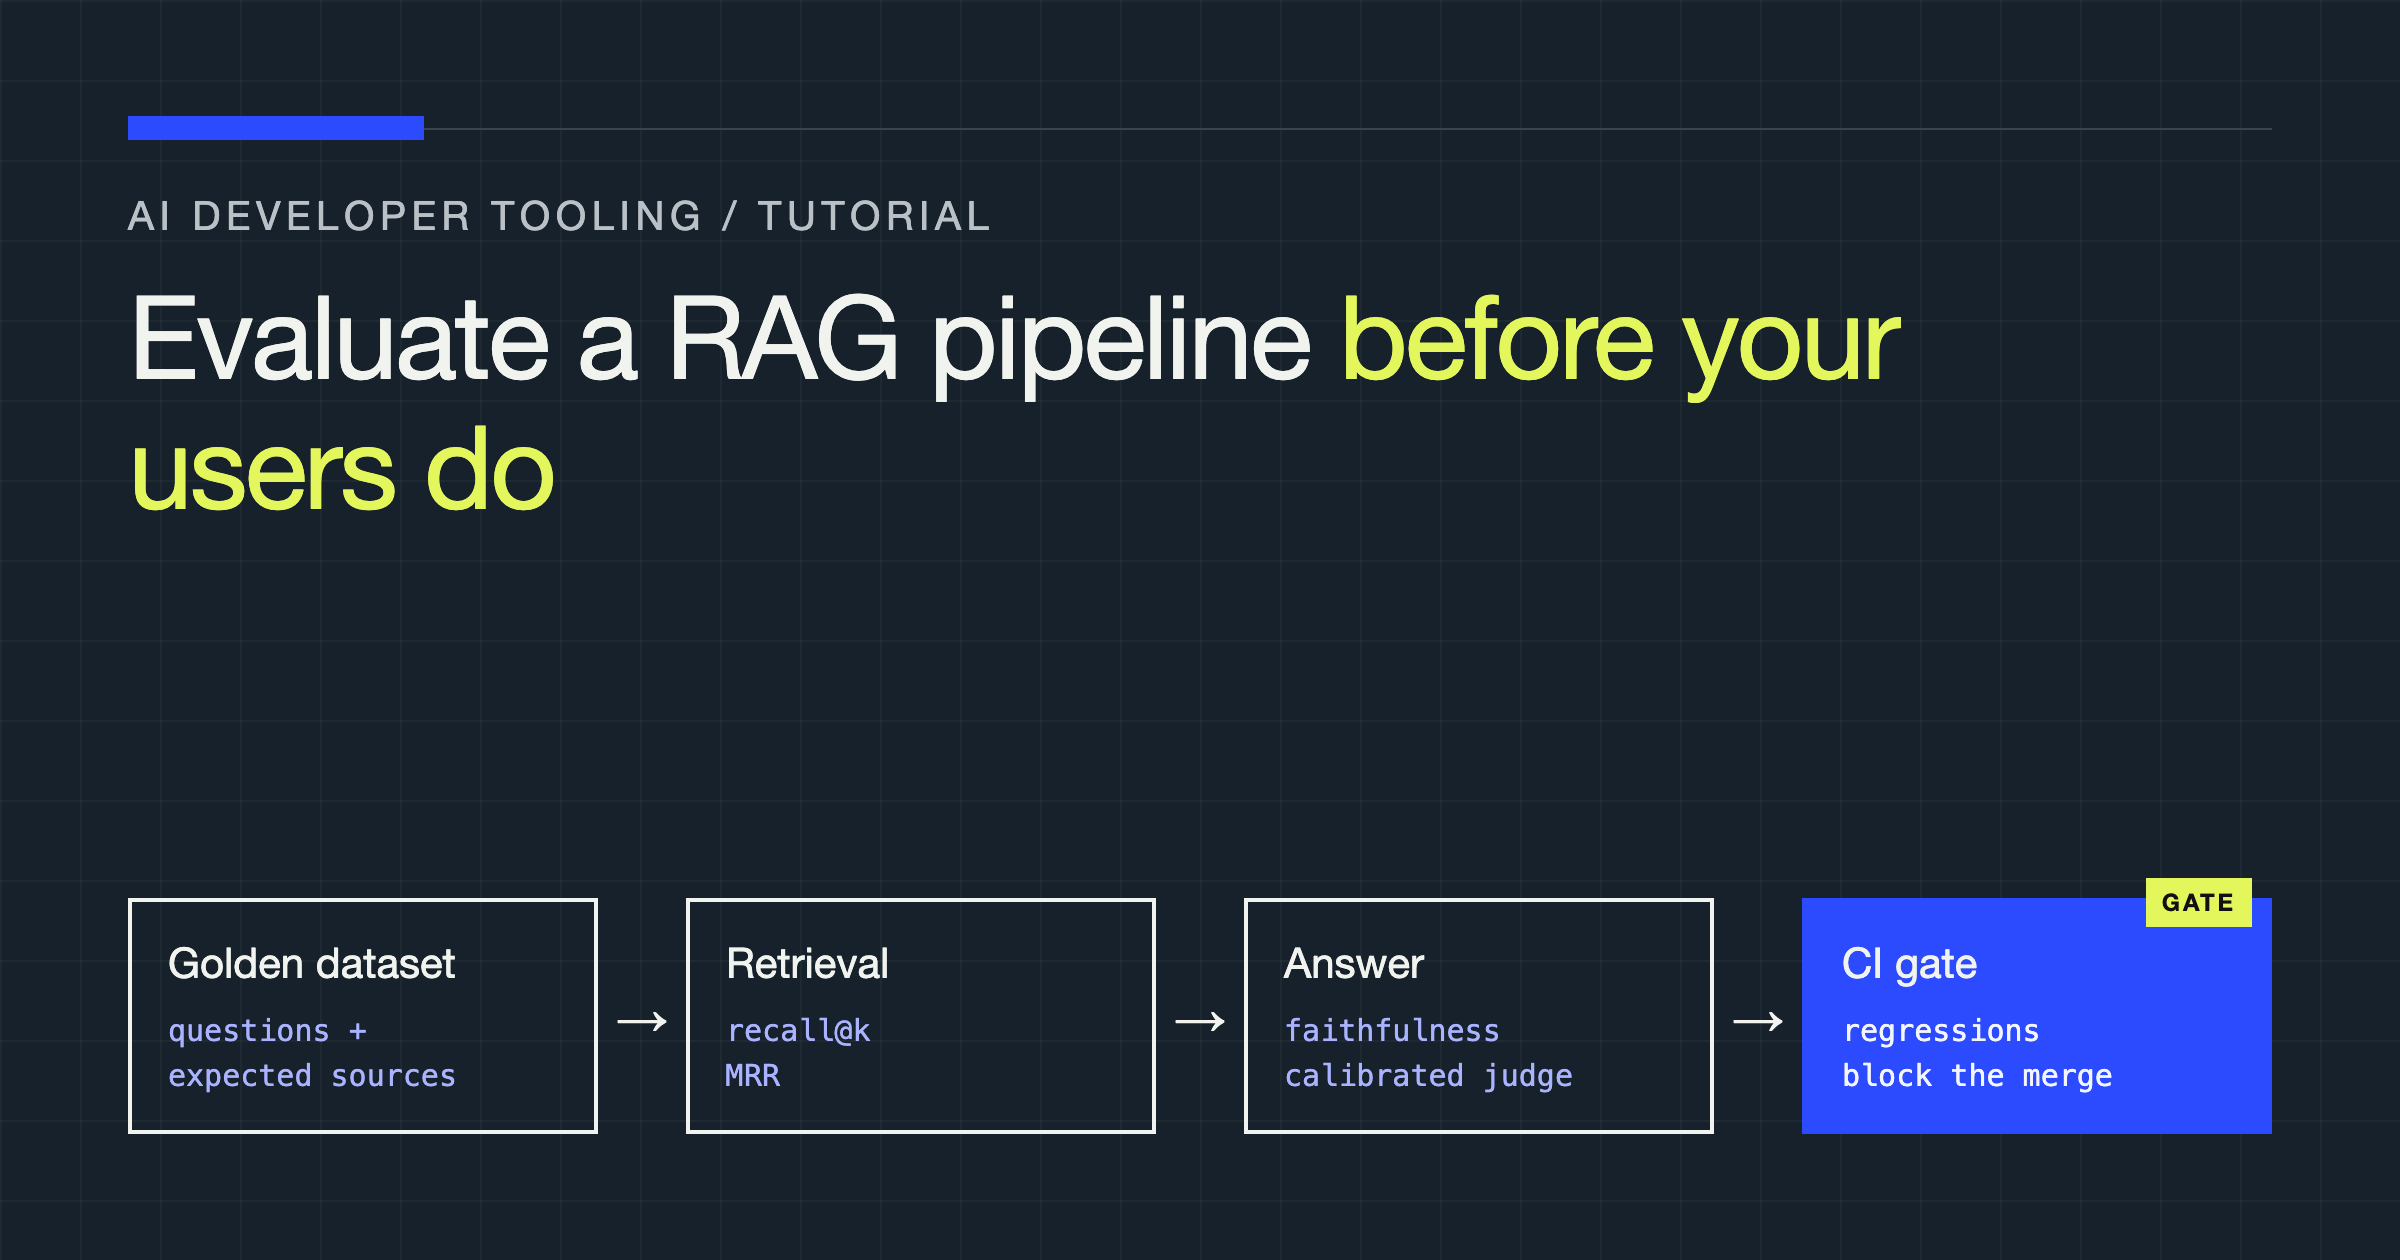
Evaluate a RAG Pipeline Before Your Users Do
Build a repeatable evaluation harness for your retrieval-augmented generation pipeline: golden datasets, retrieval metrics, faithfulness checks, and CI gates.
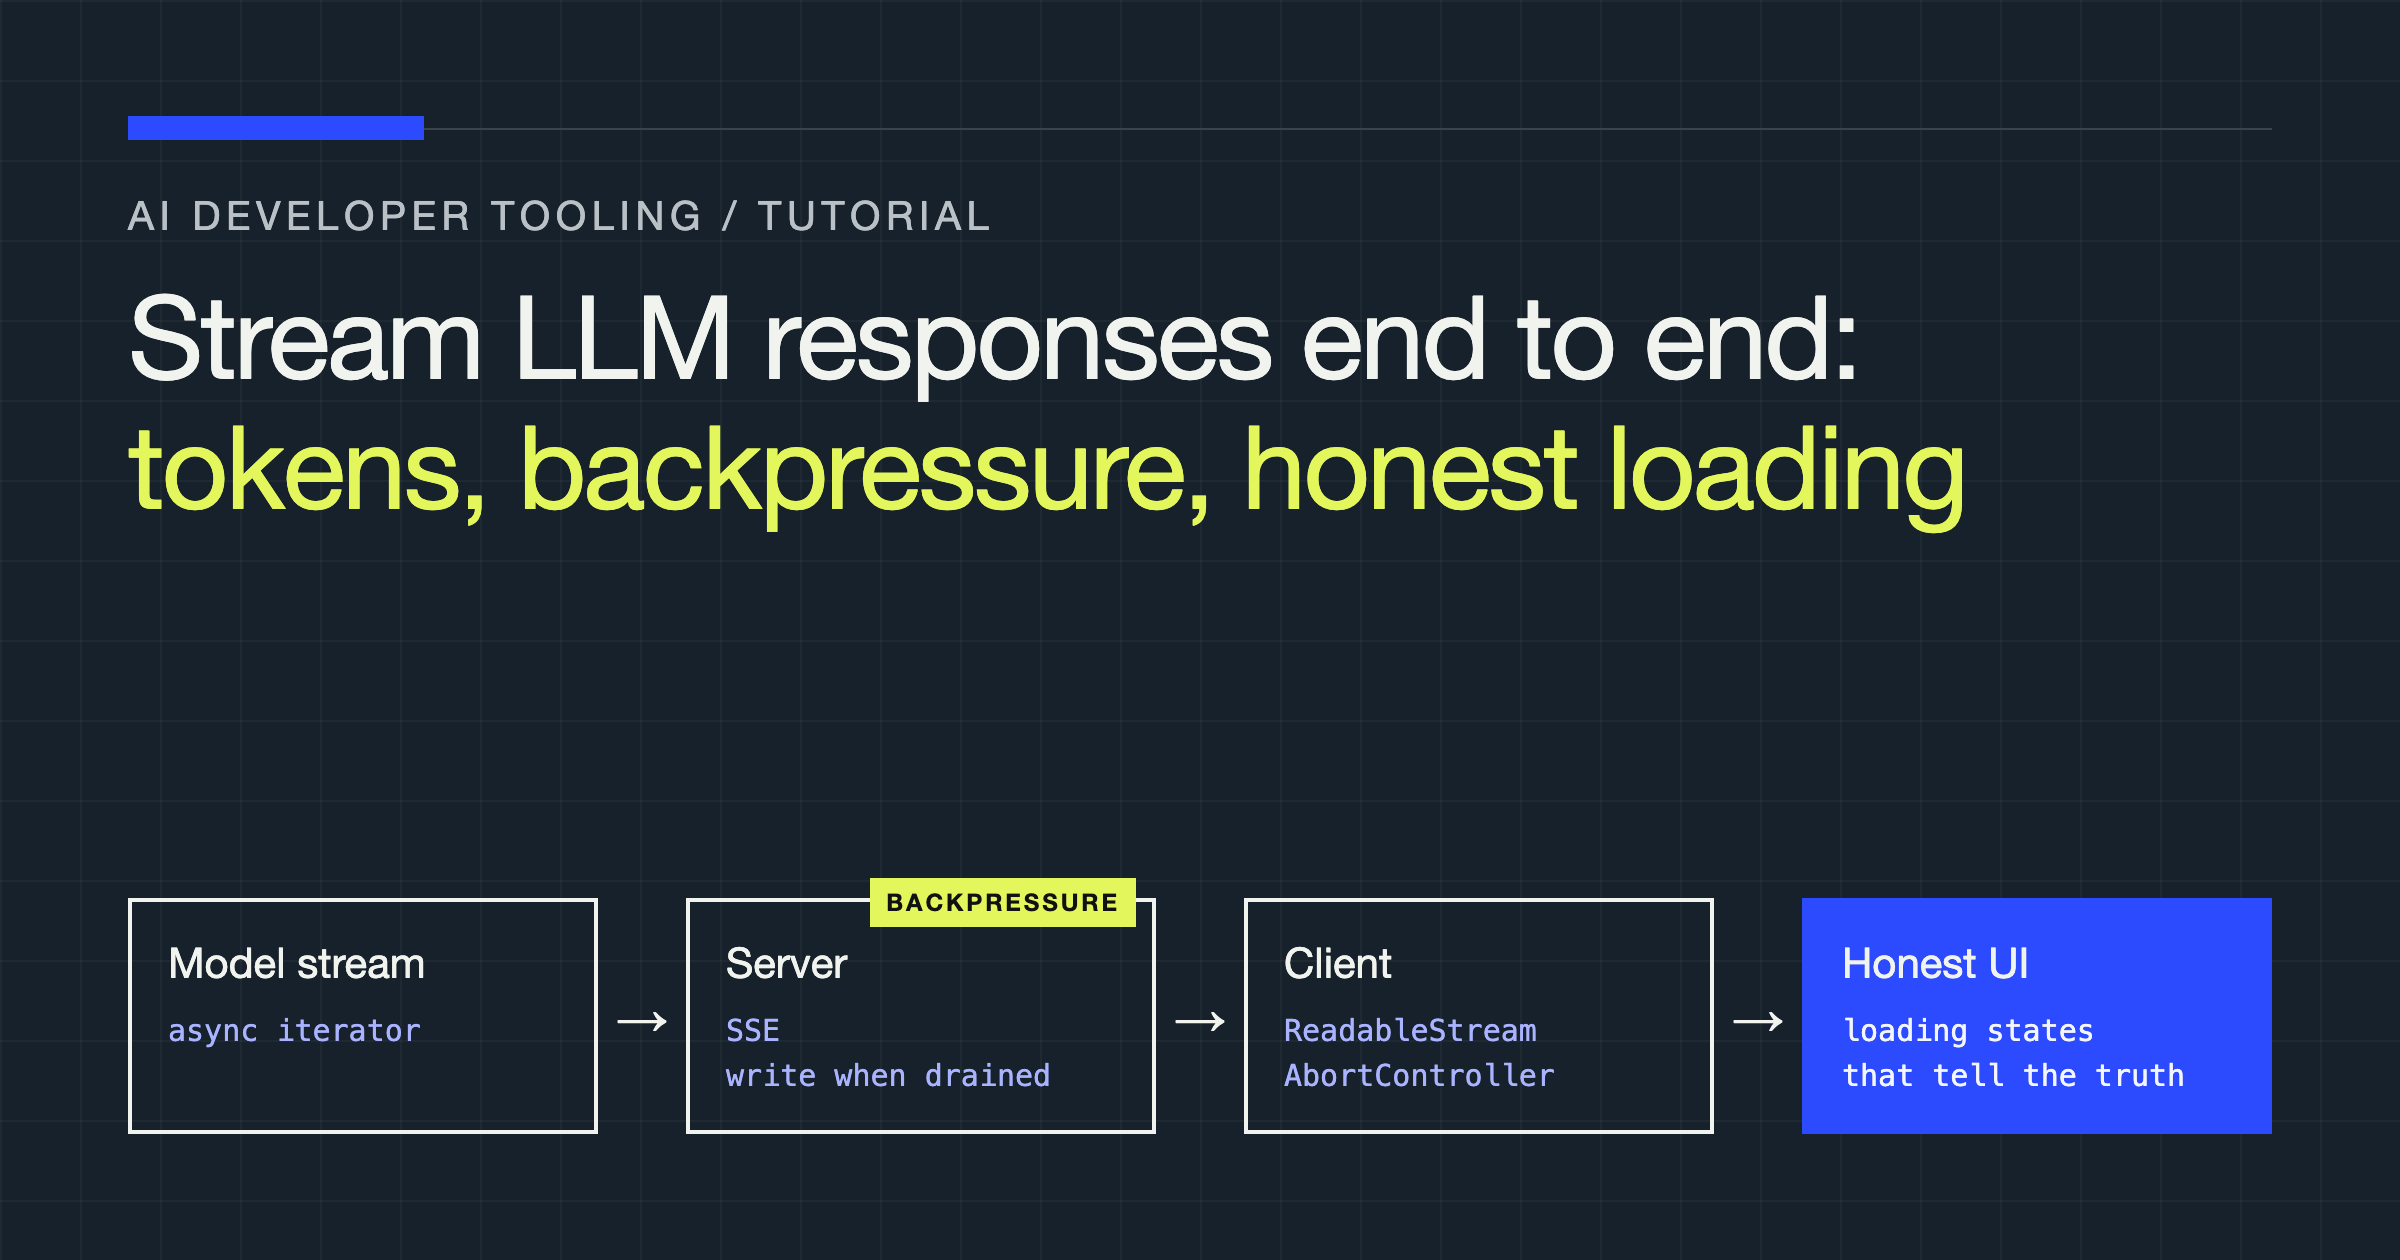
Streaming LLM Responses End to End: Tokens, Backpressure, and Honest Loading States
Build production-ready token streaming with SSE, ReadableStream, backpressure, aborts, and loading states that tell the truth.
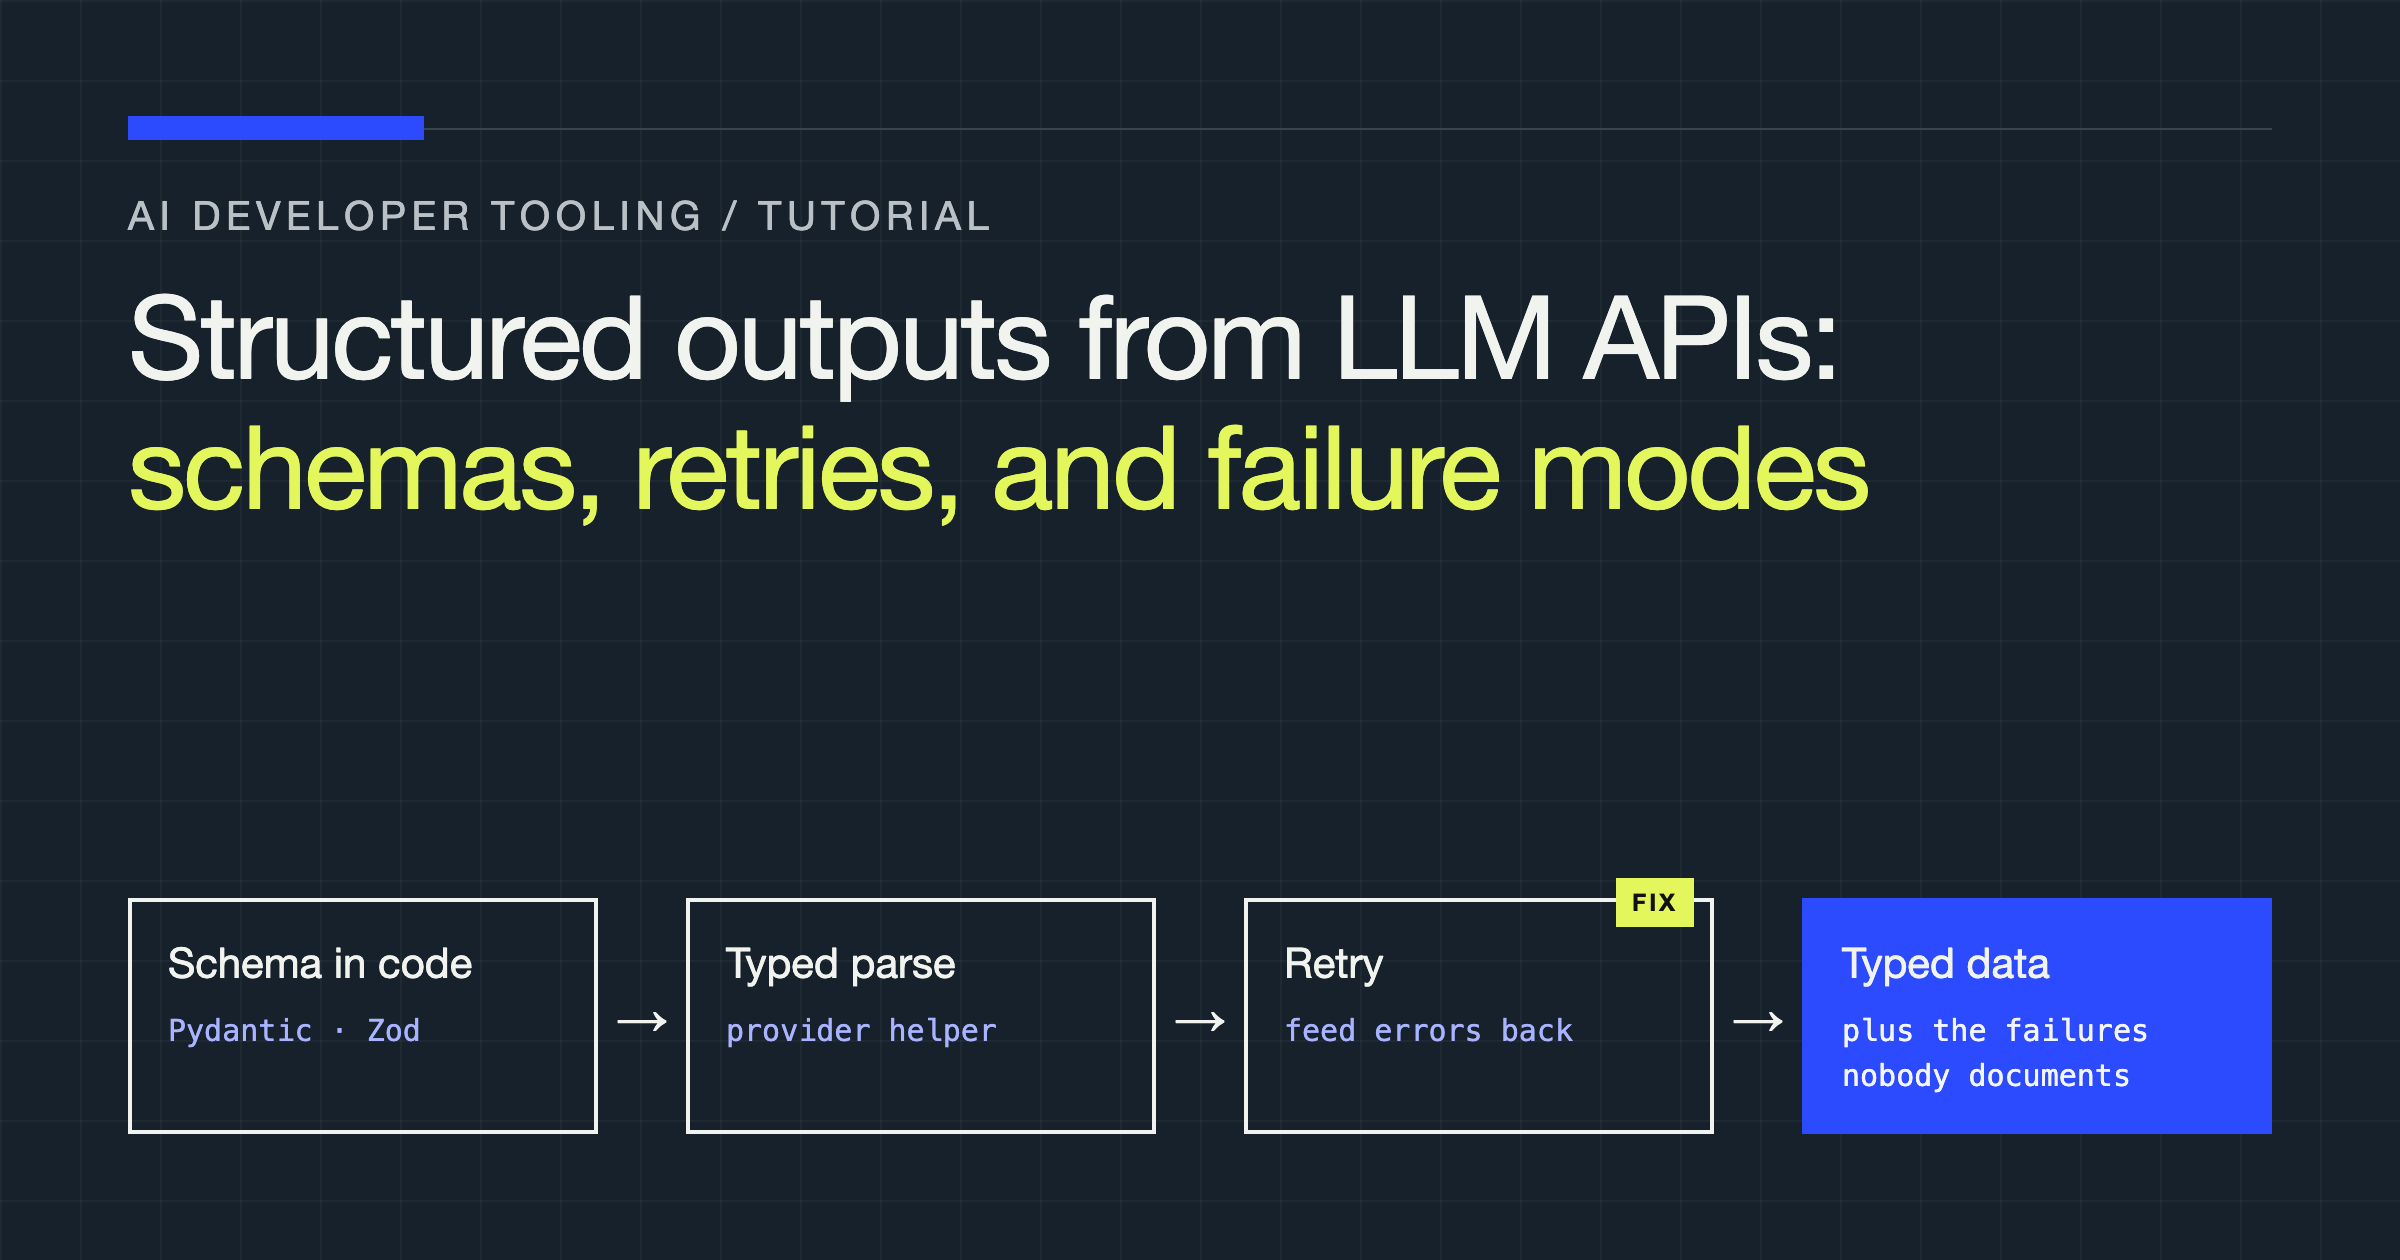
Structured Outputs from LLM APIs: Schemas, Retries, and the Failure Modes Nobody Documents
Get reliably typed data out of LLM APIs: strict schemas, parser-backed validation, retry loops that fix errors, and the failure modes that survive all three.
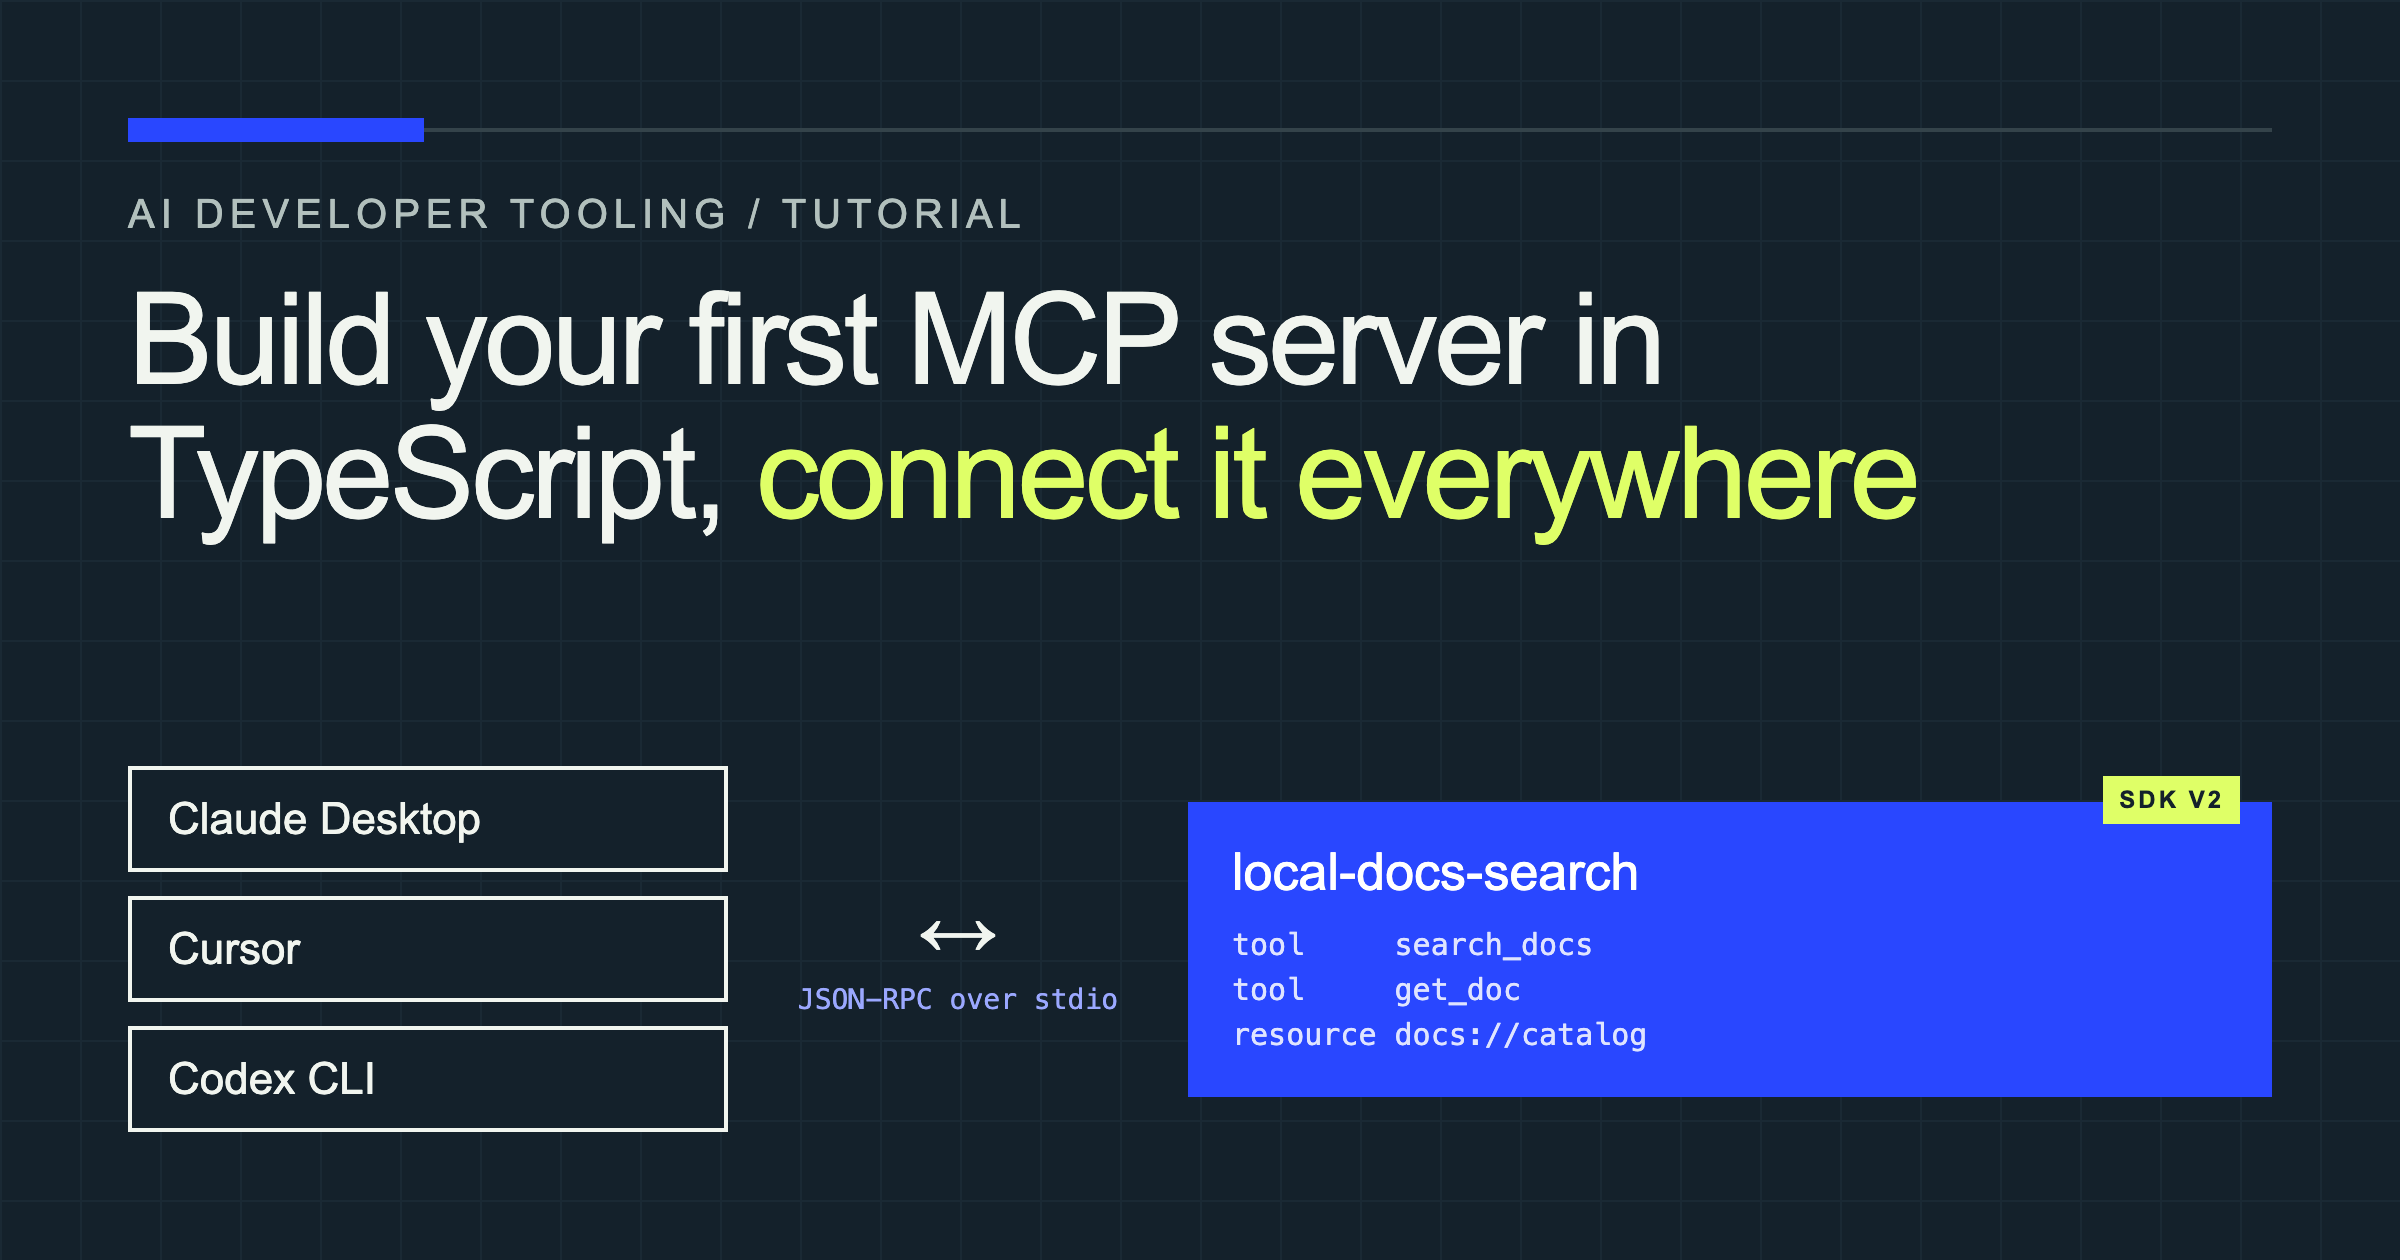
Build Your First MCP Server in TypeScript (SDK v2) and Connect It to Claude, Cursor and Codex
Build a local Markdown search server with MCP TypeScript SDK v2, test it with Inspector, and connect it to Claude Desktop, Cursor, and Codex.
No matches in this set.
Clear a filter or try another combination.